Data Engineering · TAMIL-FIRST LEARNING
Data Engineering: Build Real-Time AI Data Pipelines
Follow the flow of incoming events through processing, quality checks and delivery to an AI-ready data store. Build a complete mental model for moving raw operational data into reliable real-time data products for analytics and AI.
COURSE OFFER₹699ORIGINAL PRICE₹1,00030% off
Online self-paced course
COURSE FOCUSA monitored pipeline that delivers clean, timely and explainable data.
STRUCTUREDClear learning progression
PRACTICALApplied explanations
RESPONSIBLEHuman-validated learning
WHAT YOU WILL GAIN
Build understanding you can actually use.
See the skills this course can help you practise, then try one small example yourself.Use SQL to transform and validate data
Design quality, orchestration and recovery controls
Serve trustworthy datasets for analytics and AI
MEANINGFUL COURSE EXAMPLE
Move raw events into an AI-ready dataset
Ingest data, apply a repeatable transformation and block incomplete records before they reach analytics or AI systems.WHERE THIS SKILL FITS
See where this skill fits—and what employers expect next.
Big-data specialists and data engineering roles remain central because reliable AI and analytics depend on trusted, well-operated data.SKILL CONTEXTData remains the foundation for AI
WHAT TO PRACTISE BEYOND A COURSE
Model and query dataBuild reliable transformationsCheck quality and lineageOperate batch or real-time pipelines
These are possible directions, not a job guarantee. Check current role requirements and build practical evidence alongside the course.
TOPIC GUIDE
Understand the topics before you enroll.
This is an editorial guide to the subject, not the course syllabus. Open the current course page to see the exact lessons and any included exercises.IDEA 01
Start with the basics
- Understand the core ideas behind Data Engineering
- Learn the terms used in this field
- See where the skill fits in a real task
IDEA 02
Data Storage & Modelling
- Operational and analytical data
- Schemas, partitions and formats
- Batch and streaming concepts
IDEA 03
Build Data Pipelines
- Ingestion, transformation and delivery
- ETL and ELT patterns
- Orchestration and dependencies
IDEA 04
Reliable Data Systems
- Quality checks and observability
- Security and governance
- Scale, cost and AI readiness
HOW TO PRACTISE
Use a small example to check your understanding.
START HERE
Ingest source
Choose a small task related to the topic.
TRY NEXT
Transform records
Follow the idea and write down what happens.
TRY NEXT
Check quality
Try the next step yourself.
REVIEW
Serve trusted data
Check your result and explain what you would change.
WHO THIS COURSE IS FOR
Is this the right course for you?
Check the audience, level and course preview before you enroll.Aspiring data engineersSQL and analytics learnersDevelopers moving into data platformsAI learners who need reliable data foundations
BEFORE YOU BEGIN
Start with the right expectations.
This course is designed to remove unnecessary barriers while keeping the learning practical.Basic SQL familiarity is helpful but not mandatory
No previous streaming-platform experience required
A local database is optional for extended practice
OPTIONAL PRACTICE IDEAS
Connect the concepts in your own practice.
These are suggested exercises to try independently. Check the current course page for any assignments included with the course.Customer-order SQL model
Clean operational records, define business rules and produce an analytics-ready table.
Real-time event pipeline design
Move order events through ingestion, transformation and a serving layer with recovery rules.
AI-ready feature dataset
Create governed, time-aware features while preventing leakage and stale data.
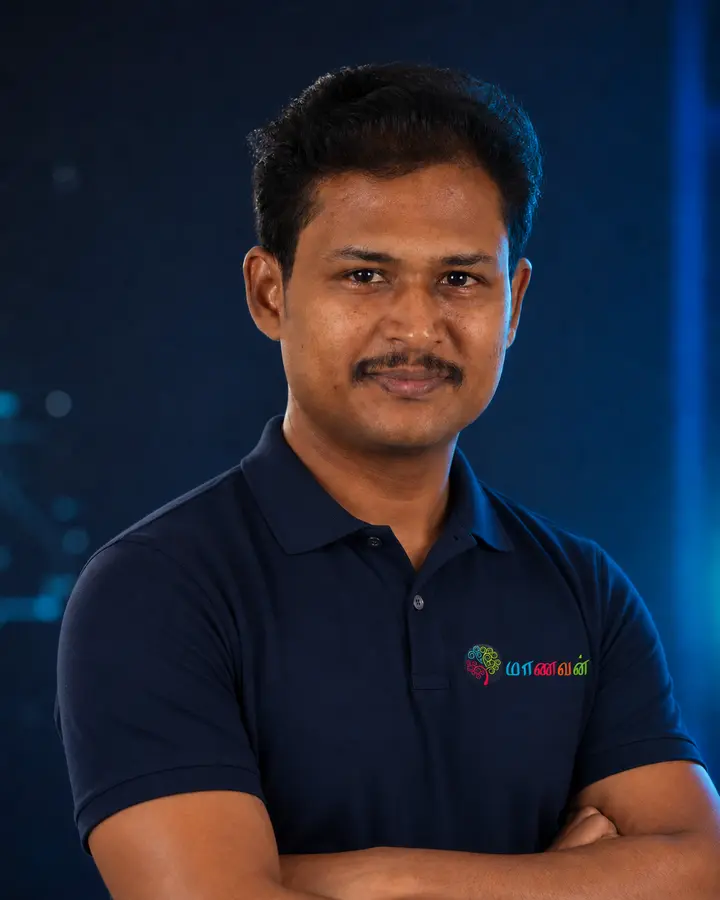
COURSE GUIDANCE & QUALITY
Learn with a Tamil-first educator’s perspective.
Founder & Chief AI Educator, MaanavaN
Course pathways are shaped to connect clear explanations, current technology practice and credible next steps for Tamil-speaking learners worldwide.
17+ years of industry and learning experience5× AI and cloud certifiedTamil-first course guidance
COURSE QUESTIONS
Answers before you begin.
Is SQL still important for modern data engineering?+
Yes. SQL remains central to transformation, modelling, quality checks and analytics across many cloud data platforms.
What is the difference between batch and streaming?+
Batch processes bounded data on a schedule. Streaming handles events continuously or in very small intervals, with additional ordering, latency and recovery concerns.
Do I need to know Apache Kafka before starting?+
No. The course introduces event-streaming concepts first. You can later apply them to Kafka or another managed platform.
How does data engineering support AI?+
AI systems need trustworthy, discoverable and timely data. Pipelines provide ingestion, transformation, quality, lineage and serving foundations.
TRUSTED LEARNING SOURCES
Continue with authoritative documentation.
Use these sources to verify concepts, follow current platform guidance and deepen your practice beyond the course.READY TO BEGIN?